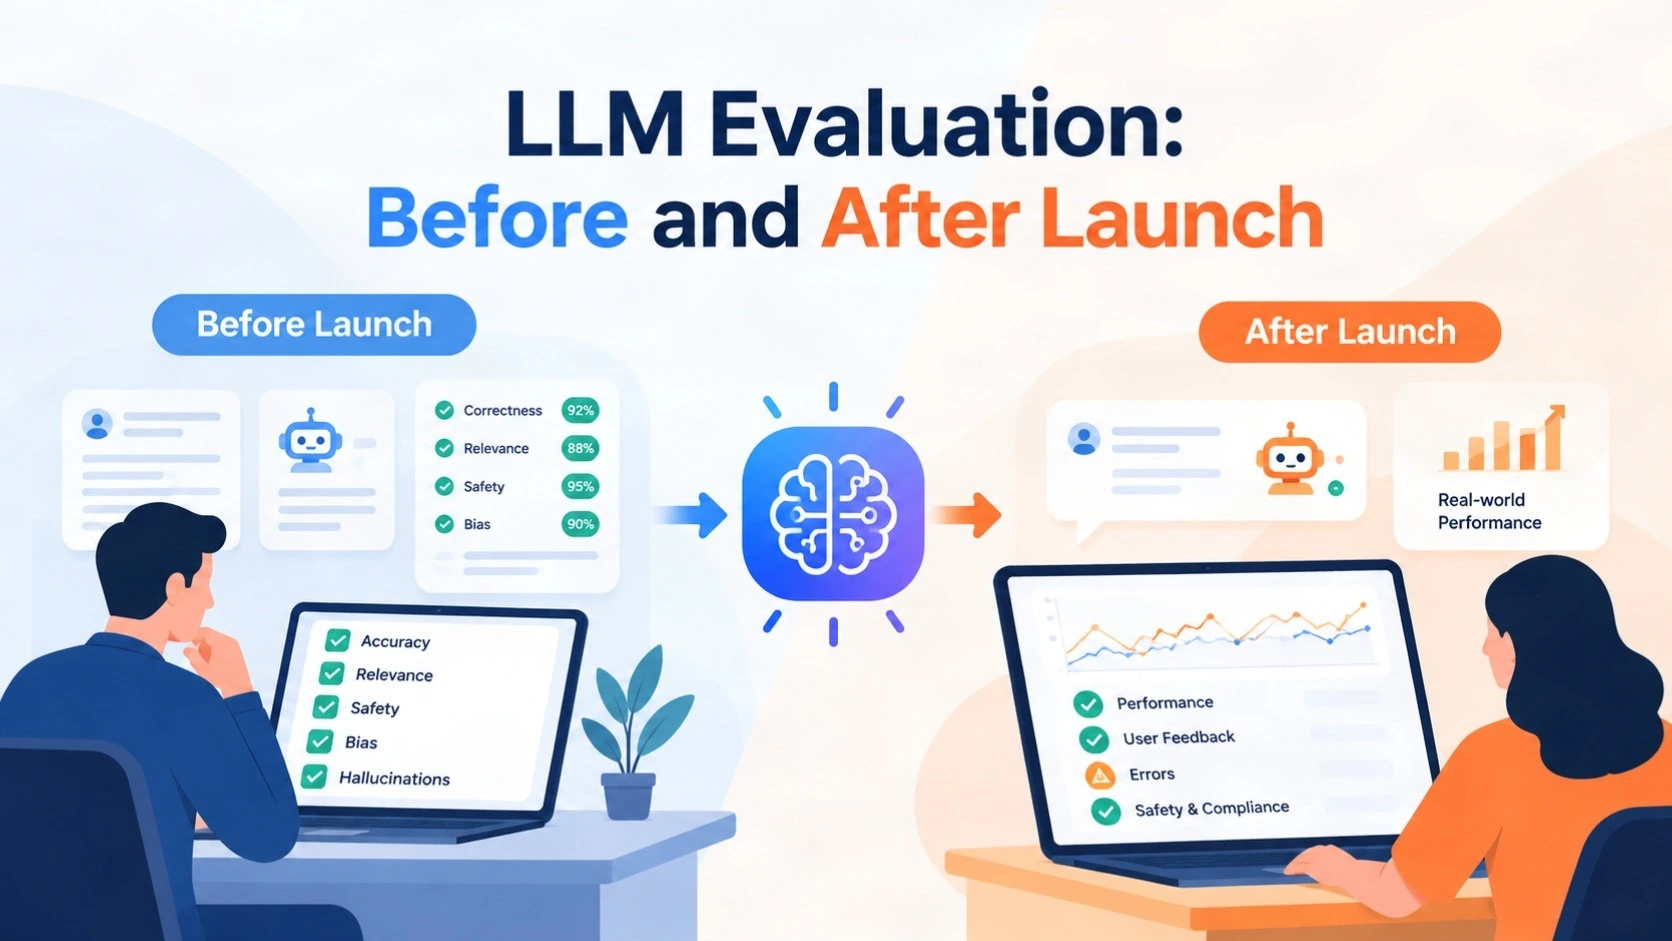
LLM Evaluation: How to Test AI Apps Before (and After) They Ship
Pranav LakhaniOctober 30, 2026
Share this article


Let AI highlight what matters.
The chatbot from customer service answers 45 of the 50 test queries correctly. The team is pleased with the results and implements the chatbot.
Three days after launch, a client inquires about refund exceptions, and the chatbot provides misinformation confidently even when accurate information is available in the company’s documents.
The issue stemmed, however, from more than just the model itself. Other factors could have contributed to the problem, such as ineffective document retrieval, unclear instructions, or even the lack of a test case.
This is exactly why LLM evaluation matters.
Testing a limited number of queries can help understand how well AI can perform under ideal circumstances, rather than revealing the application’s ability to cope with unanticipated questions, contradictory information, sensitive data, or changes to the algorithm
LLM evaluation refers to the act of identifying the extent to which the large language model in question provides correct, proper, and helpful outcomes.
A good evaluation process covers four areas:
Any AI applications require two types of evaluation. The first one assesses performance in controlled conditions. The second type measures the effect of the application on real users.
Offline evaluation consists of running an application with a predetermined set of test cases without giving live users any exposure to the revisions made. Three methods are frequently applied.
Golden datasets are collections of validated instances that carry inquiries, the expected answers, and evaluation techniques.
The goal is not to come up with a specific answer but to ensure that the provided answer correctly conveys the right notion.
In this method of evaluation, another language model is used to evaluate the content of the output based on a scoring system.
For example, a judge might score factual accuracy on a scale of 1 to 5:
| Score | Evaluation |
| 1 | Incorrect or misleading |
| 2 | Major information missing |
| 3 | Mostly correct, but incomplete |
| 4 | Accurate with minor issues |
| 5 | Accurate, complete, and supported |
Not every outcome requires the use of a different AI model.
The code can check if the response is formatted correctly in terms of JSON, fulling the required schema, etc.
Humans know better how to evaluate complex business decisions, vague responses, as well as delicate cases.
Use of these two methods guarantees wider coverage than if using one of them only.
Online assessment is the process of assessing performance in real life.
The two common methods of conducting online assessment are:
While offline assessment can help to identify possible failures of the system, online evaluation allows detecting issues not shown in controlled data sets.
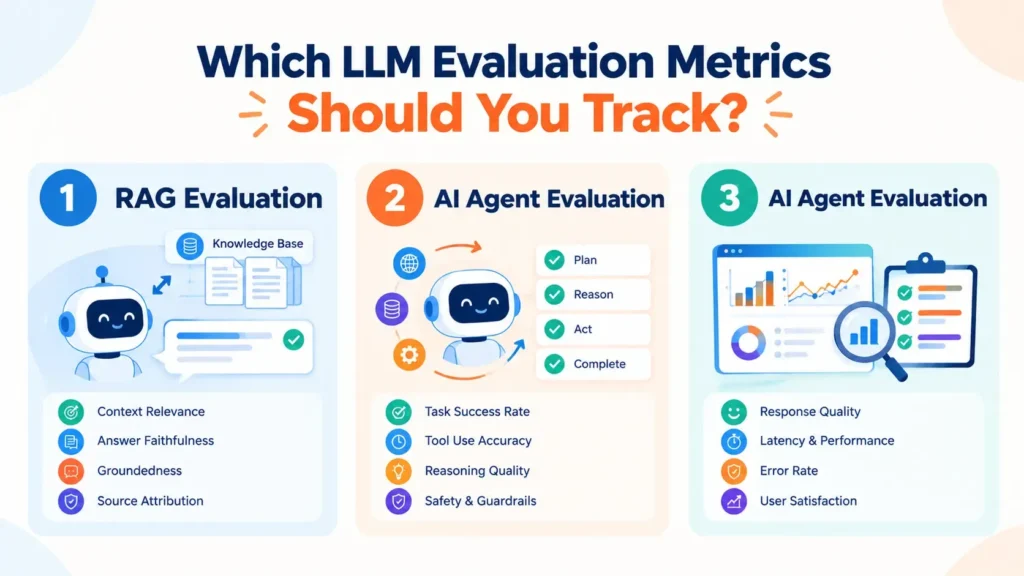
The right metrics depend on what an application is expected to accomplish.
Retrieval-augmented generation (RAG) applications fetch information from external documents or databases before generating an answer.
For a detailed explanation of these stages, read our RAG pipeline implementation guide.
Effective RAG evaluation should measure:
Artificials abilities are not confined to simply creating text. Additionally, they conduct many activities such as building knowledge, calling APIs, and updating systems, and handling complicated business processes.
Accelerate agent evaluation by checking the following:
Conversational applications demand more checks because some individual replies can be correct while the overall experience is frustrating.
Important measures include:
| Application | Primary quality measures | Additional checks |
| RAG assistant | Faithfulness, retrieval precision, correctness | Source citations, document access |
| AI agent | Task success, tool accuracy | Recovery, permissions, action logs |
| Chatbot | Helpfulness, relevance, consistency | Escalations, multi-turn behavior |
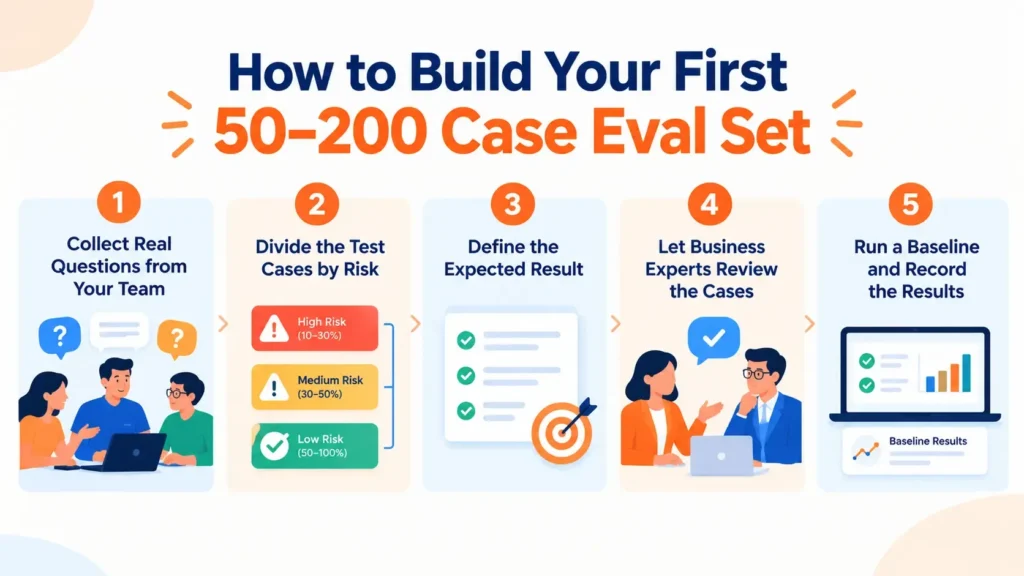
Below is a guide on how to construct one using your business expertise.
Start from consumer service logs, internal records, product FAQs, and prevalent work requests.
Inquire with people who are most knowledgeable about the procedure:
For an initial 100-case dataset, consider this allocation:
| Test category | Cases | Purpose |
| Common requests | 40 | Verify routine performance |
| Complex questions | 20 | Test reasoning and multiple conditions |
| Edge cases | 20 | Check ambiguous or incomplete inputs |
| Safety and permissions | 10 | Identify unsafe or unauthorized behavior |
| Previous failures | 10 | Ensure known problems remain fixed |
| Total | 100 | Initial evaluation coverage |
Every case should have sufficient detail for another verifier to know what a good outcome is.
A usable data set can include the following fields:
| Field | Example |
| Case ID | HR-024 |
| User input | “Can I withdraw an approved leave request?” |
| Reference source | HR Policy, Section 4 |
| Expected behavior | Explain cancellation conditions |
| Evaluation criteria | Accuracy, completeness |
| Risk level | Medium |
| Reviewer | HR team member |
Developers know about software architecture. Business people know what the right output should be. Both views are important.
Run the existing application against every case and save the outputs.
Suppose the first test produces:
The original success rate is reported at 86%.
The team now monitors outcomes from this benchmark.
Always take the dataset, rules of scoring, version of the model and version of the prompt together. It will be hard to compare the performance in different rounds of testing otherwise.
An app can lose its reliability although the developers believe they improved it.
The modified prompt can deal with one problem but simultaneously create another. For example, the new model can be much quicker in giving feedback but be less accurate in following directions.
Changing document chunking is one of the things that may change the quality of retrieval.
Regression testing is used to verify that the application remains true to its own standards after the change is introduced.
A practical release workflow looks like this:
A release gate is a rule that determines whether a new application version can proceed.
Consider these figures for an internal knowledge assistant:
| Measure | Proposed release requirement |
| Overall test success | At least 95% |
| Faithfulness | At least 0.95 |
| Critical permission violations | Zero |
| Response latency | P95 below 4 seconds |
| Cost per request | Within the approved budget |
| Known critical regressions | Zero |
Succeeding in the first test phase is just the beginning. Actual clients ask their questions in a different way, changes take place in corporate documents, API fails functioning, and discussions may contain situations the programmers have not predicted.
So, it is the moment when it is crucial to apply production monitoring.
The platform for observing LLM can help teams track logs, acquired documents, responses of the model, and metering of different parameters. However, observing and evaluating are not the same things.
Imagine a customer service representative who misunderstands a new returns policy.
The team should:
Thereby, a feedback loop is established, which ensures that production problems increase the testing universe.
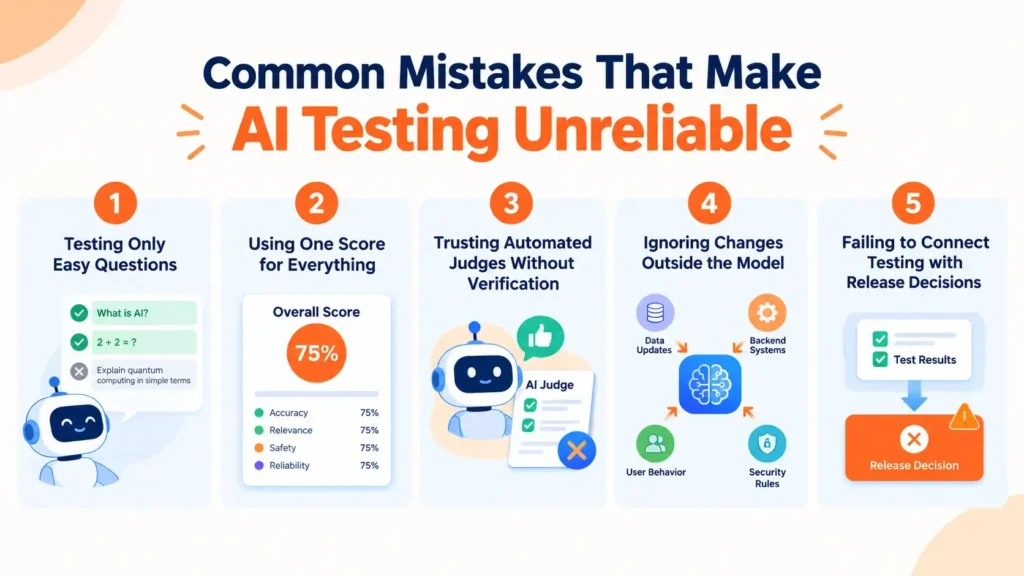
Despite the fact that the testing process is clearly defined, it can still deliver distorted results if it is improperly designed.
If all assessments consist of standard questions, the system might succeed in the testing process but fail to solve real issues that customers have.
Take into consideration unclear instructions, contradictory documents, unaccessible instruments, and incomplete information when evaluating.
A chatbot with high-quality response can nevertheless leak information that should be secret or use wrong tools.
Look at important risks separately, rather than number them in just one overall quality score.
An AI judge might miss factual mistakes or promote certain writing styles.
Compare its results with human judges, figure out why they disagree, and reassess rubric regularly.
The model works not only according to its prompts.
Documentation updates, search indexes, access rules, API integrations, workflow processes, and so on might cause a malfunction.
The whole system should be tested, and not only the output of the last phase’s results.
Evaluation reports have limited value if deployments proceed regardless of the results.
Document who can approve a release, what constitutes a critical failure, and when the team must roll back a change.
Use this checklist before giving the go-ahead to an AI-driven functionality for production.
Our guide on how to choose AI agent development company explains why asking vendors to demonstrate their test cases and execution traces is important before making a purchasing decision.
Creating applications with AI technology requires more than an ability to provide correct answers. It is essential to implement tangible measures of quality, conduct repeat tests, and identify malfunctions when business requirements are altered.
NextGenSoft assists companies in implementing language models into their systems, databases, and operations.
Our LLM integration services comprise different steps: choosing a model, creating prompts, validating structure of output, testing , optimizing performance, and monitoring production.
Connect now to discuss your architecture, testing requirements, and production readiness.
1. What is the best way to evaluate an LLM application?
Answer: Start by clarifying what results an application is expected to achieve. Next, create the necessary dataset, set measurement systems, and integrate automated checks with human reviews.
2. How many test cases are needed for reliable AI evaluation?
Answer: A specific application can be created using around 50-200 thoroughly analyzed test cases. In general, more advanced systems usually require a bigger dataset, especially if they use sensitive data, outside APIs, or involve several stages of the working process.
3. What is the difference between testing RAG applications and AI agents?
Answer: RAG testing concentrates on whether the system is able to sift through necessary evidence and receive answers backed with that proof. In addition, agent testing also investigates what tools have been chosen and how tasks have been performed.
4. Can LLM-as-a-judge replace human reviewers?
Answer: Not really. Automated judges can efficiently evaluate a great amount of answers, but results might not be either accurate or reliable.
5. How frequently should companies run evaluation tests?
Answer: The company should conduct offline regression testing every time when there are changes in the prompt or the model or the process of retrieval of the necessary information.
 Pranav Lakhani
Pranav brings over 20 years of expertise in software development and design, specializing in delivering enterprise-scale products. His unique ability to manage the entire product lifecycle ensures innovation and technical excellence across every project.
We’re ISO/IEC 27001:2022 certified, ensuring your projects are executed with globally recognized security standards.

INDIA
 sales@nextgensoft.io
 +91 81284 66678


